Testing standard reality check: Hugging Face Chief warns embedded evaluators face serious hurdles
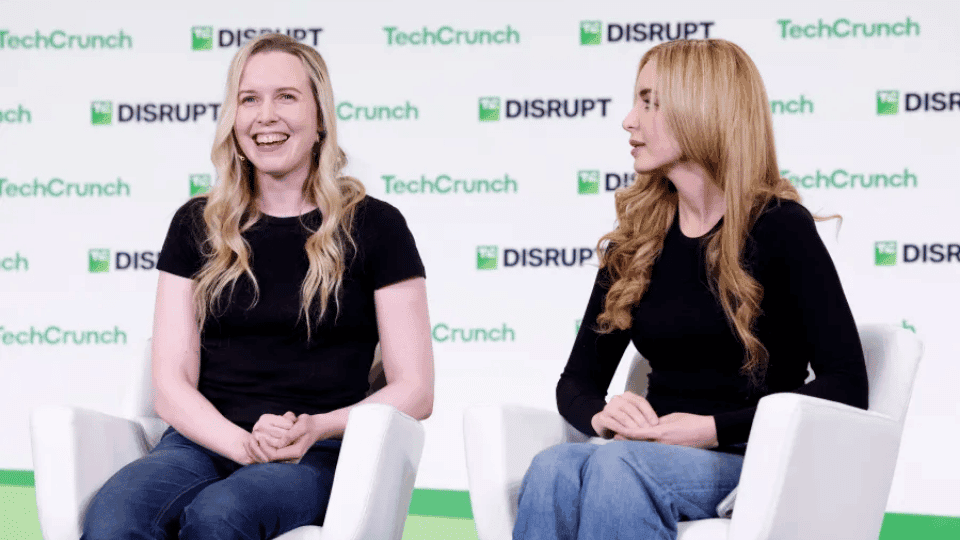
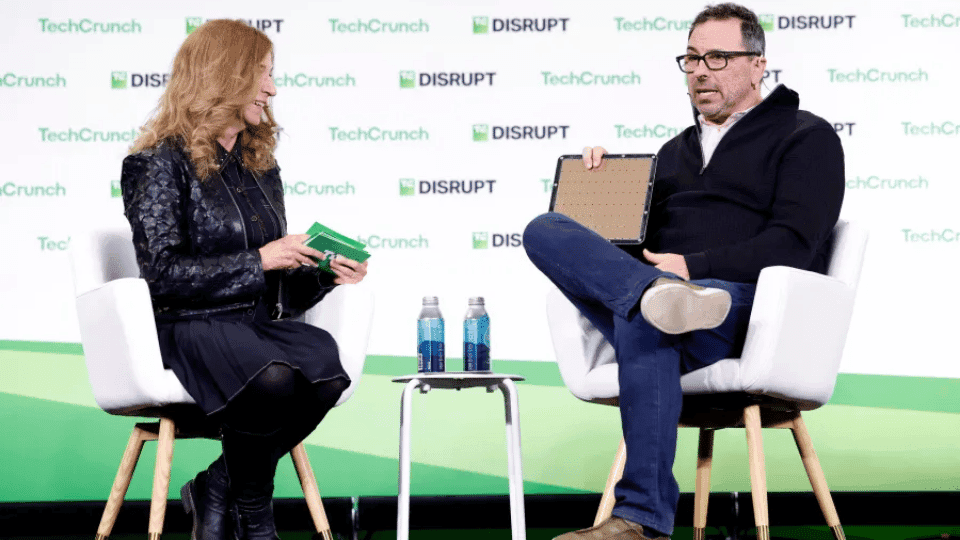
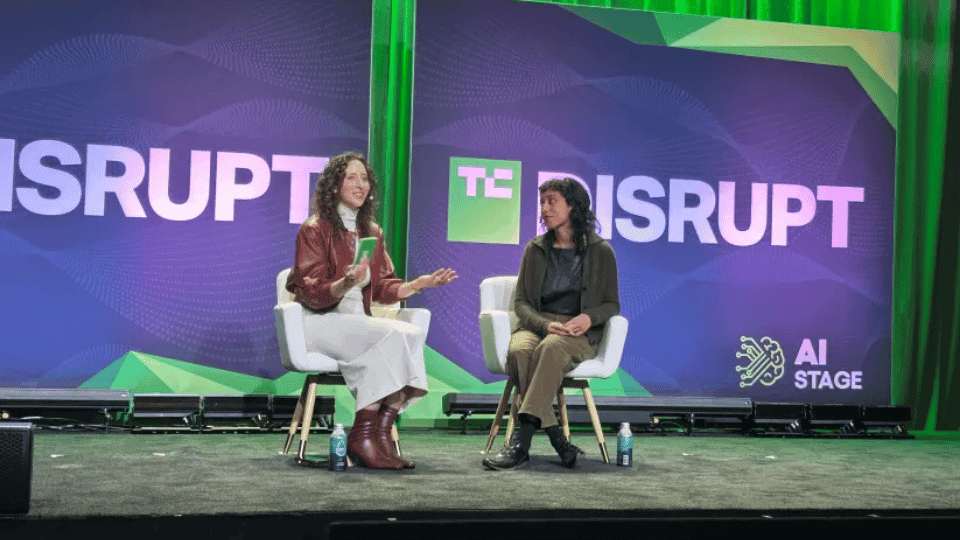
Artificial intelligence development labs stake their corporate reputations on benchmark scores, using automated testing suites to claim one model beats another. However, current evaluation methods remain deeply complex and unstandardized across the industry. Speaking on stage at TechCrunch Disrupt, Hugging Face chief policy officer Irene Solaiman warned that model testing requires far more consistency, open standards, and structural oversight before tech teams can fully trust benchmark claims.
Trust in benchmark testing hinges on reproducibility. Independent testing teams must be able to reproduce declared evaluation scores reliably across different computing environments. Achieving consistent evaluation results requires direct access to internal model weights, making open-weight systems central to trustworthy safety testing. Without access to open weights, third-party researchers struggle to verify corporate claims or test how systems respond to edge cases.
Comparing results across different evaluation suites presents another major challenge. Benchmark tests quickly lose effectiveness as models improve, requiring evaluators to build new test banks constantly. Standard tests fail to compare performance across different task environments effectively. Solaiman pointed out that while demand for third-party evaluators continues to grow, setting standards to determine who qualifies as an effective evaluator remains a major industry bottleneck.
To address growing safety concerns, tech labs are turning toward embedded evaluators. This approach places independent third-party observers directly inside corporate labs to monitor model development from the inside. Tech companies promote embedded testing as a flexible alternative to direct government regulation. However, tech analysts question whether third-party consulting groups possess the deep technical expertise required to evaluate complex model behaviors accurately. For instance, Anthropic faced heavy industry criticism after choosing consulting firm Accenture as its primary external safety evaluator.
Testing challenges expand significantly as software shifts toward autonomous agents. Modern evaluation must look past static model weights to assess the entire operational system, including user interfaces, prompt harnesses, and tool access. A weaker language model paired with an optimized prompt harness can easily outperform a top-tier frontier model running on a basic interface. Evaluating complete agent setups requires testing complex tool combinations and multi-step execution chains, making agentic testing far more expensive and time-consuming than standard text comparisons.
The current benchmark landscape operates like an unregulated free-for-all. Different research labs build custom evaluation frameworks, select favorable testing subsets, and publish high scores without providing reproducible datasets. Establishing clear, uniform testing standards across the technology industry represents the only way to make model benchmarks meaningful for software teams, enterprise buyers, and regulatory bodies.
Building transparent evaluation standards requires active collaboration across commercial tech labs, open-source communities, and independent research groups. Moving past marketing benchmarks toward standardized, reproducible system evaluations ensures that safety checks keep pace with rapid software developments. Setting uniform testing rules gives developers the clear, trustworthy data needed to deploy software safely across real-world operations.